Chips & SupplyUnited States
CoreWeave targets AI inference bottlenecks with full-stack optimization
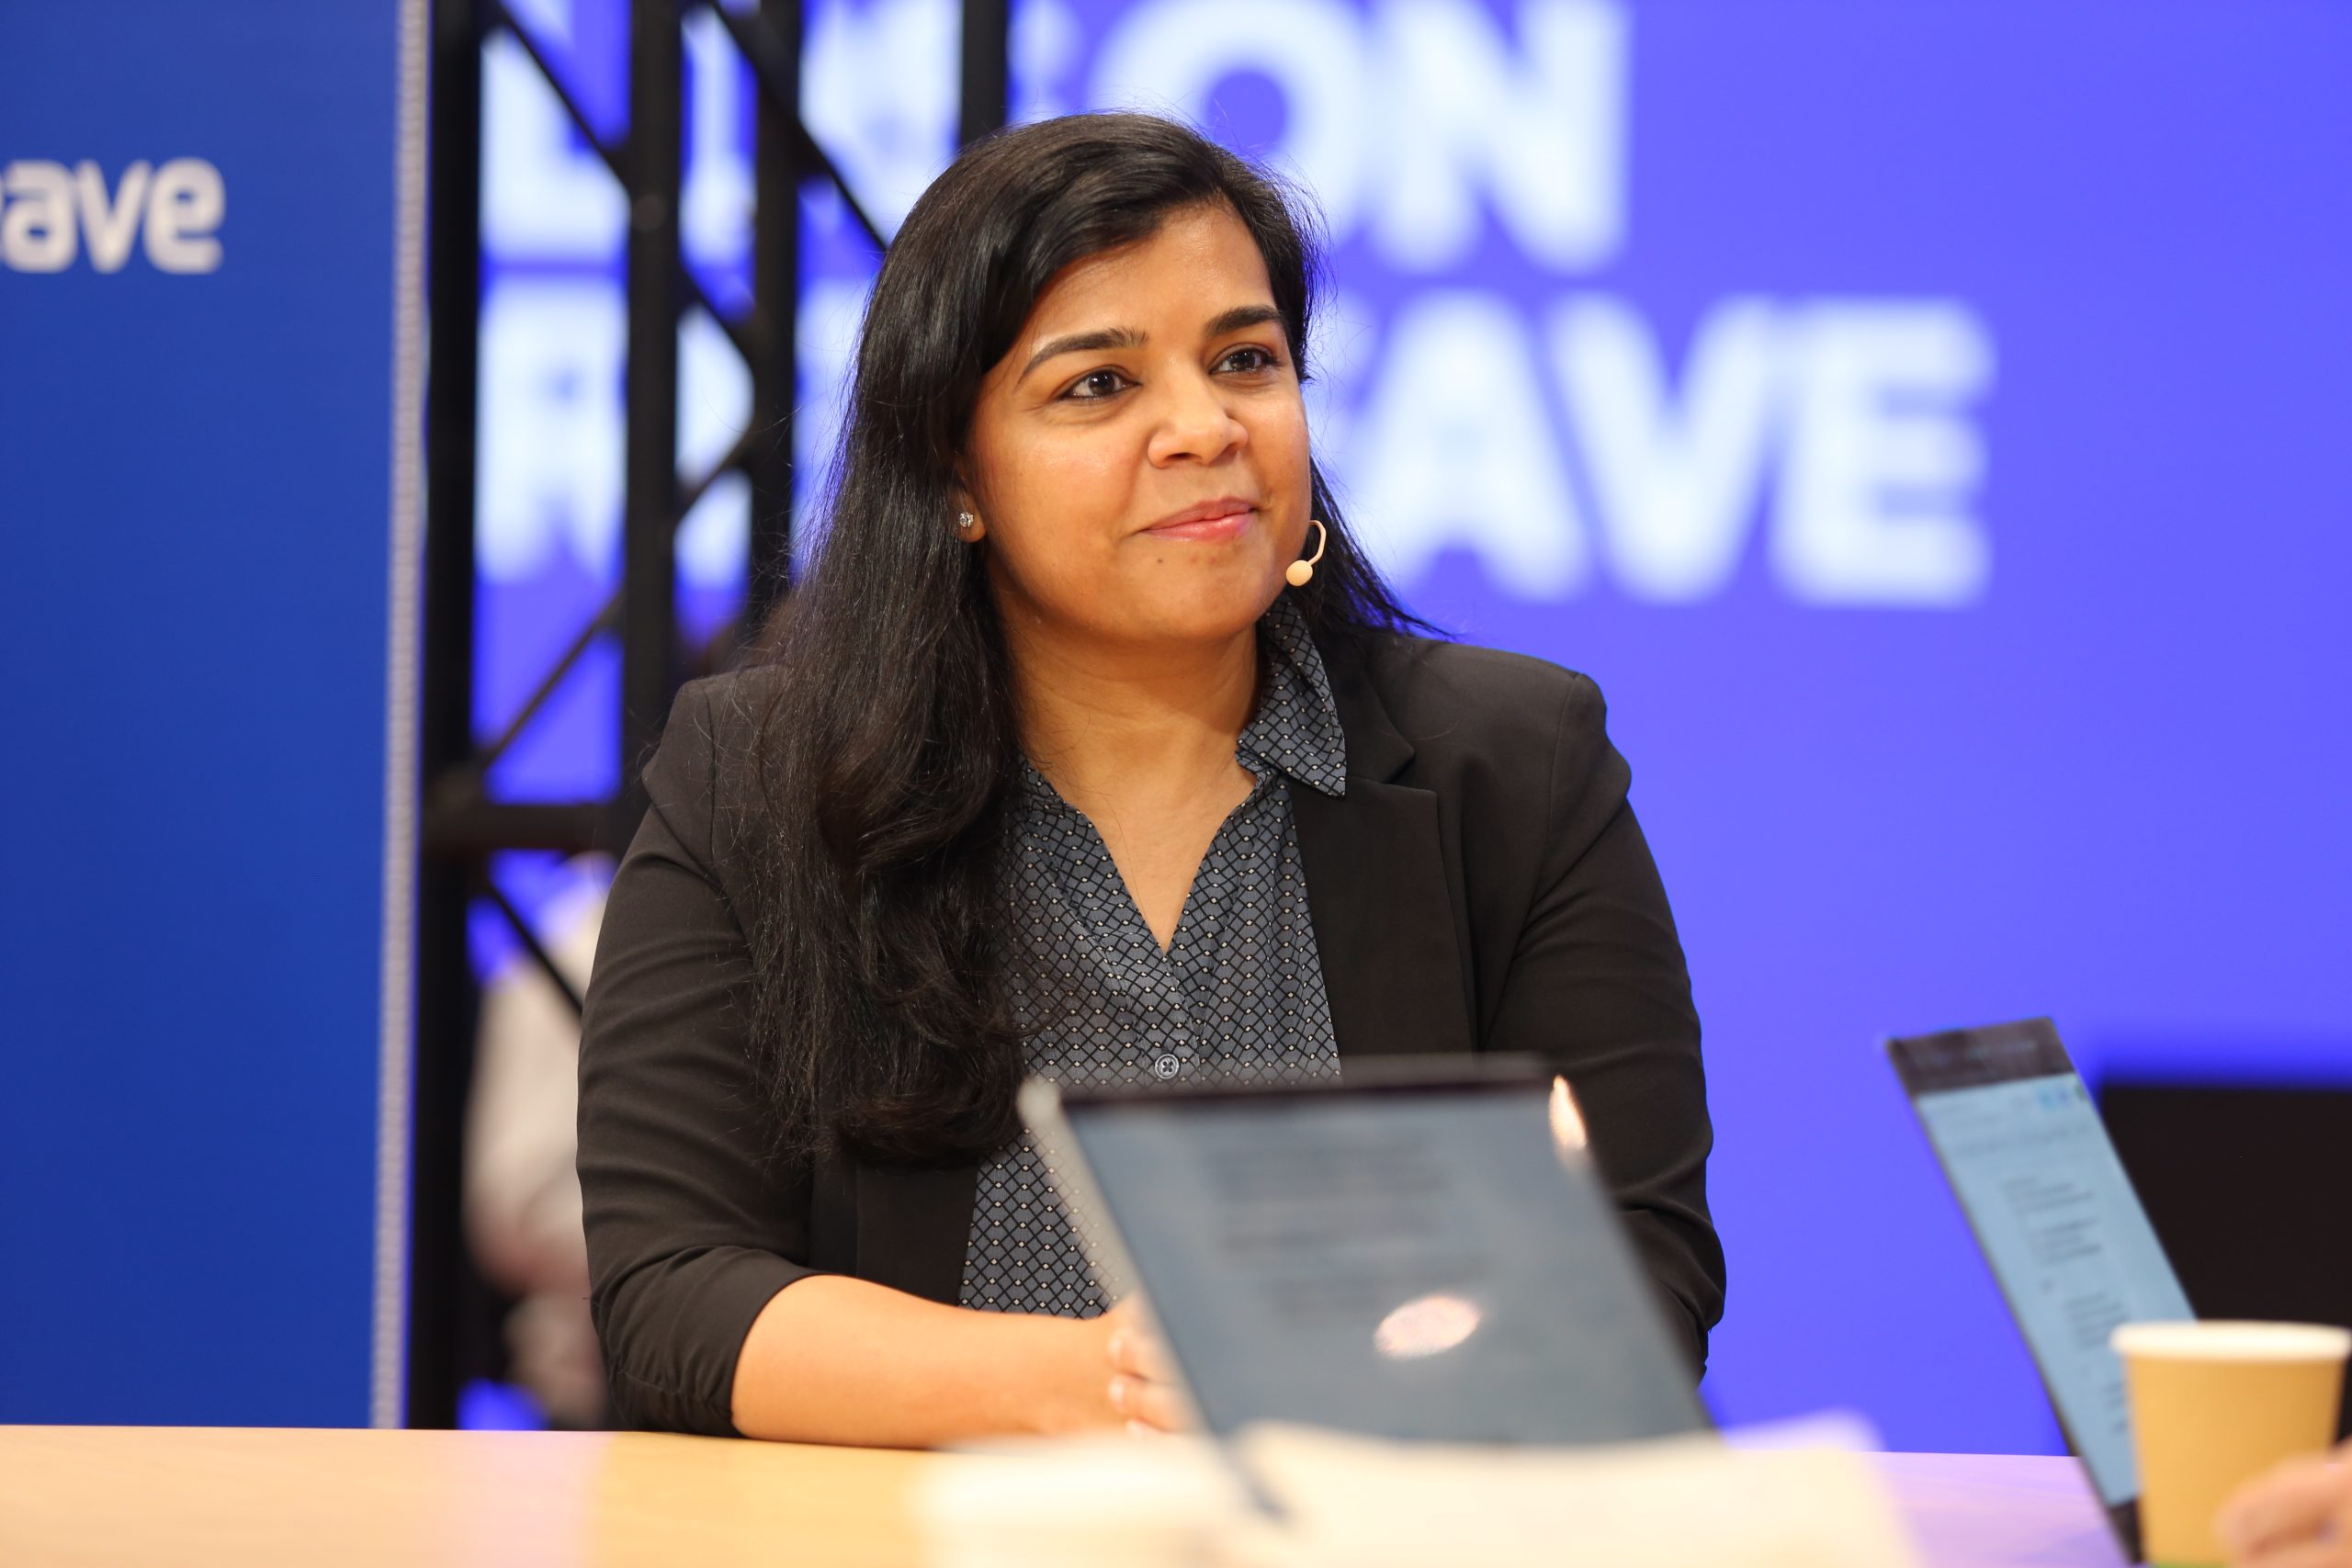
AI inference is fast becoming the workload that decides the economics of the AI boom. Training built the first wave of GPU clouds, but serving models faster and cheaper will define the next.
That shift is pushing specialized cloud providers beyond raw GPU capacity into storage, networking and software. One provider is layering managed services for training, post-training and inference atop its infrastructure, according to Urvashi Chowdhary (pictured), vice president of product and AI services at CoreWeave Inc.
“I think if you look at the AI developer’s journey, they’re looking to solve a problem and they want to do it as quickly as they can with the best performance and the cost to scale,” Chowdhary said. “So, we’ve been really focused on building up the layers of our stack, building on top of the reliable infrastructure to build more managed services, whether it’s for training, post-training, inference.”
Chowdhary spoke with theCUBE Research’s Dave Vellante and John Furrier at the Fully Connected event, during an exclusive broadcast on theCUBE, SiliconANGLE Media’s livestreaming studio. They discussed AI inference, managed services across the full stack and CoreWeave RL Rollouts, a new capability designed to accelerate agentic model iteration. (* Disclosure below.)
Optimizing the AI inference stack layer by layer
Inference demand is climbing fast. A survey of CoreWeave customers and prospects by theCUBE Research found one healthcare customer’s inference workload share rose from about 10% in the first year to 40% in the second, with a roughly 50% share expected within 12 months. CoreWeave’s answer is tuning every layer above the hardware, from the vLLM engine to quantized models and custom speculative decoders, Chowdhary explained.
“One thing that we’ve been very intentional about is leveraging open source tools and technologies, contributing back to open systems so customers have flexibility and then also building our services on top of each other,” she said.
Reinforcement learning adds new pressure. When customers train agentic models with rewards and verifiers, inference becomes the bottleneck during rollouts, according to Chowdhary. CoreWeave RL Rollouts, a preview capability built on Nvidia Corp.’s Dynamo framework, loads new checkpoints into a live deployment. In testing, the capability improved model reload latency by 15x compared with a baseline configuration.
“When you’re doing RL rollouts, you’re continually creating new model checkpoints and versions and you want those to roll out into your inference setup so you can scale it independently,” she said. “And we were able to speed that up by 15x, which means your training runs fast and your inference is scaling while you’re continuing to train your model quickly.”
Those capabilities now sit inside CoreWeave Forge, a platform launched at the event that connects serving, observability, post-training and evaluation. Forge is free to start, with paid tiers offering additional capabilities, extending access to AI development tools and services to individual developers, Chowdhary explained.
“We want to create accessibility for these leading technologies,” she said. “Even if you’re an individual developer signing up today on your own, you still get the best performance, you still get the best reliability and you don’t have to compromise.”
Here’s the complete video interview, part of SiliconANGLE’s and theCUBE’s coverage of the Fully Connected event:
(* Disclosure: TheCUBE is a paid media partner for the the Fully Connected event. Neither CoreWeave, the sponsor of theCUBE’s event coverage, nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)
Support our mission to keep content open and free by engaging with theCUBE community. Join theCUBE’s Alumni Trust Network, where technology leaders connect, share intelligence and create opportunities.
Are you an AWS customer? Support SiliconANGLE financially by buying your AWS services from our Marketplace portal page and links: https://siliconangle.com/aws-marketplace/
Founded by tech visionaries John Furrier and Dave Vellante, SiliconANGLE Media has built a dynamic ecosystem of industry-leading digital media brands that reach 15+ million elite tech professionals. Our new proprietary theCUBE AI Video Cloud is breaking ground in audience interaction, leveraging theCUBEai.com neural network to help technology companies make data-driven decisions and stay at the forefront of industry conversations.
White House bars Microsoft from sponsoring green card applications as JD Vance accuses it of fraud
AI stocks crumble on report that OpenAI's annualized revenue is much lower than believed
Gallatin AI raises $50M in funding for its military logistics platform
Elastic's AlertZero puts AI agents to work on security alert overload
Anthropic launches critical infrastructure program and free OSS Scanner for open source
Alphabet spinoff Isomorphic Labs reportedly raising funding at up to $50B valuation
SECURITY - BY DUNCAN RILEY. 11 HOURS AGO
SECURITY - BY DUNCAN RILEY. 12 HOURS AGO
Join our community